You’ll learn how modern Data Engineering systems are designed, developed and optimised—from writing SQL queries and processing data with Python to building scalable pipelines using PySpark, Databricks and Snowflake.
The focus is not limited to watching tool-based lessons. You’ll understand architecture, solve practical assignments, build end-to-end projects and prepare for real Data Engineering interview scenarios.
By following the complete learning path, you will work on:
• SQL for Data Engineering and interviews
• Python, files, APIs and ETL development
• Data Modelling and Data Warehousing
• Pandas for data cleaning and transformation
• PySpark and distributed data processing
• Delta Lake and Lakehouse Architecture
• Databricks workflows and orchestration
• Snowflake, Streams, Tasks and ELT
• BigQuery, GCS and cloud migration
• Data Engineering system design
• Resume, GitHub and interview preparation


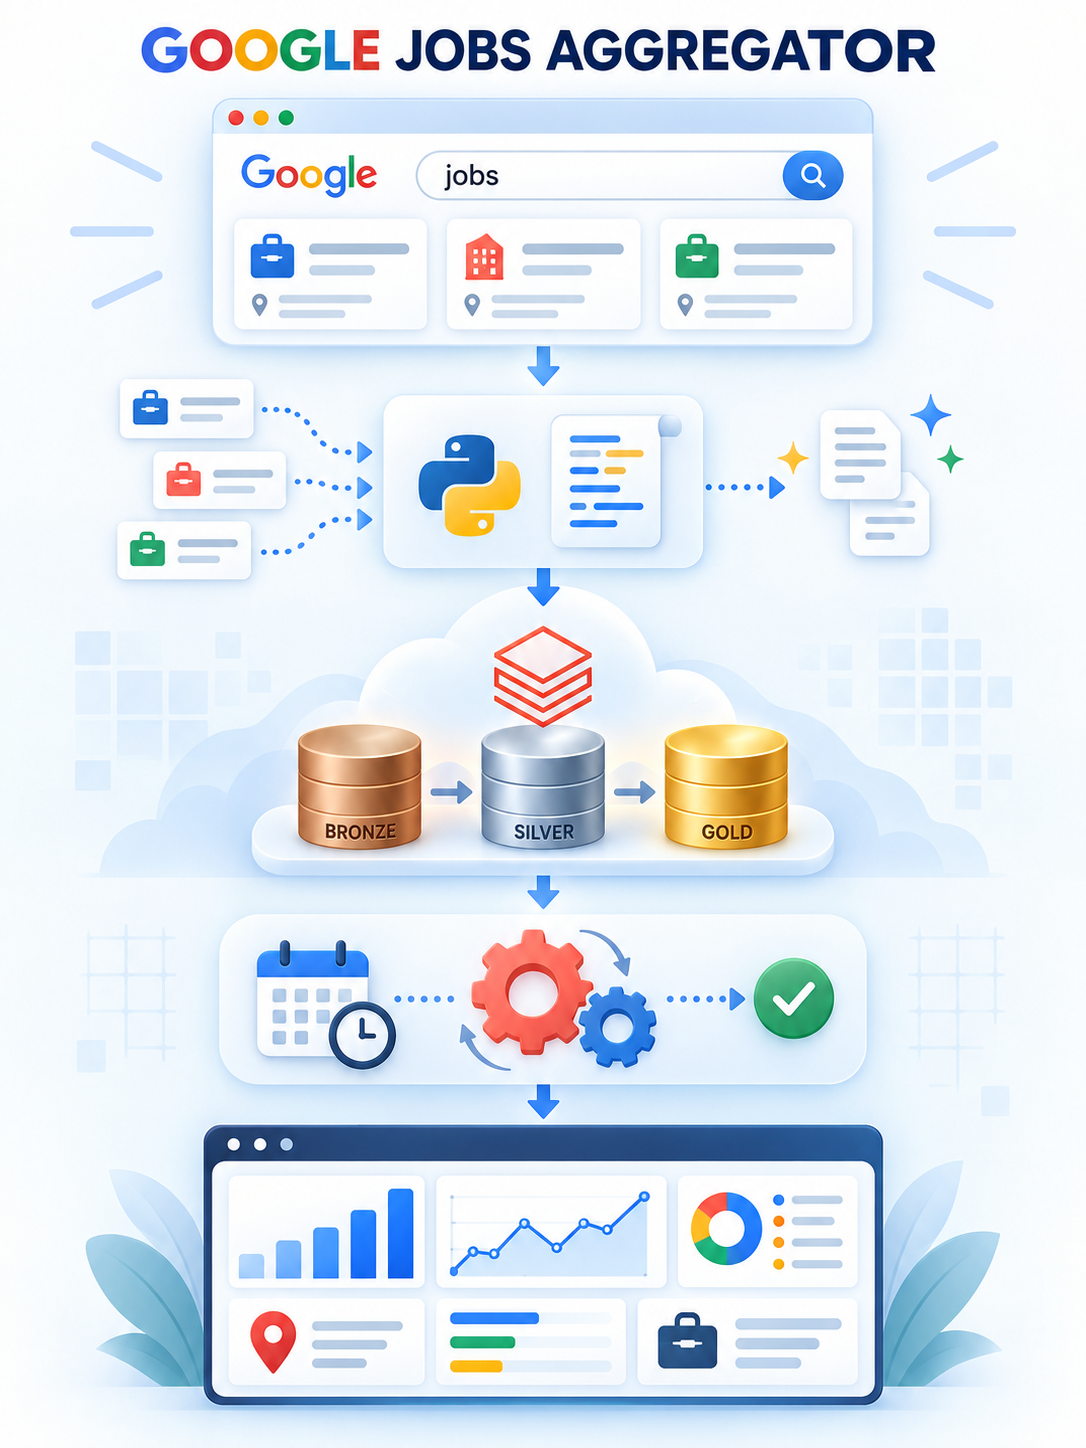
Google Jobs Aggregator: End-to-End ETL Pipeline
Design and build a complete Data Engineering pipeline from scratch.
• Understand the business requirement
• Design the complete pipeline architecture
• Ingest data from files and APIs
• Clean and transform the data
• Build Bronze, Silver and Gold layers
• Automate the pipeline using Databricks Workflows
• Create job-market insights using Databricks SQL
Technologies Used: Python, Pandas, PySpark, Databricks, Delta Lake, Databricks Workflows and Databricks SQL

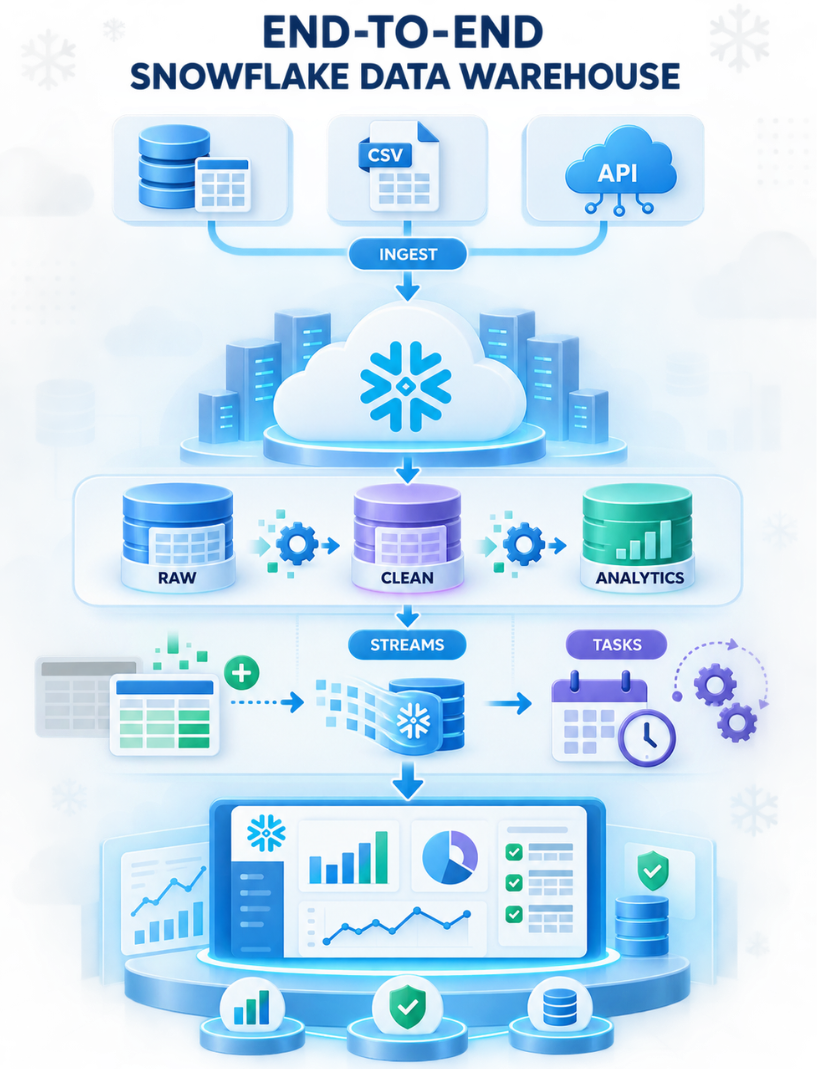
End-to-End Snowflake Data Warehouse Project
Build a complete analytical Data Warehouse pipeline using Snowflake.
• Understand Snowflake architecture
• Ingest data into Snowflake
• Build cleaning and transformation layers
• Implement incremental data processing
• Automate pipelines using Streams and Tasks
• Design a production-ready Snowflake workflow
Technologies Used: Snowflake, SQL, ELT, Snowflake Streams, Snowflake Tasks and Data Warehouse Modelling

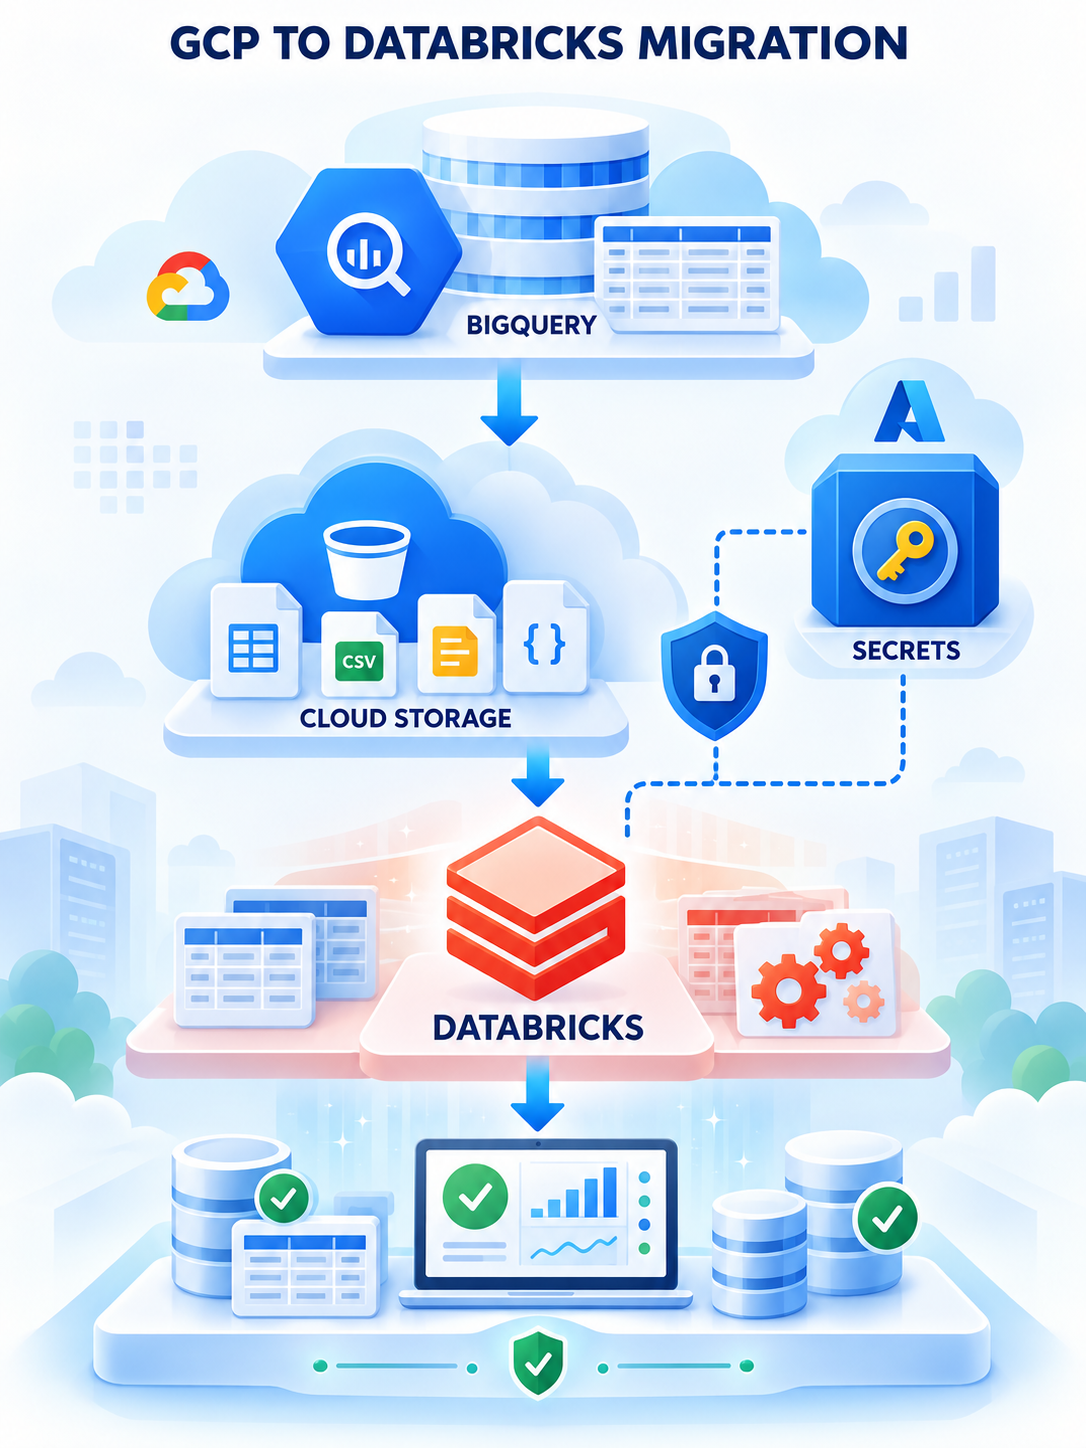
Understand how a real cloud data migration project is planned and implemented.
• Work with BigQuery source data
• Move data through Google Cloud Storage
• Load and process data in Databricks
• Handle cloud credentials securely
• Understand the complete migration architecture
• Learn production-level migration considerations
Technologies Used: Google Cloud Platform, BigQuery, Google Cloud Storage, Databricks, PySpark, Delta Lake and Azure-based Secret Management


Yes, 100% self-paced. You can learn anytime, at your convenience, without any deadlines.
Yes, it's designed for complete beginners. You’ll learn everything from scratch — no prior experience required.
You’ll work hands-on with SQL, Python, Pandas, PySpark, Delta Lake, Databricks, PandasAI, and more — all focused on real job work.
Yes, you'll get a certificate of completion. But more importantly, you’ll have job-ready skills and real projects to showcase.
Yes. You’ll complete end-to-end projects including data cleaning, ETL pipelines, and dashboards — all added to your GitHub portfolio.
This is not just video lectures. It’s a practical, structured, interview-focused bootcamp taught by a working Data Engineer.